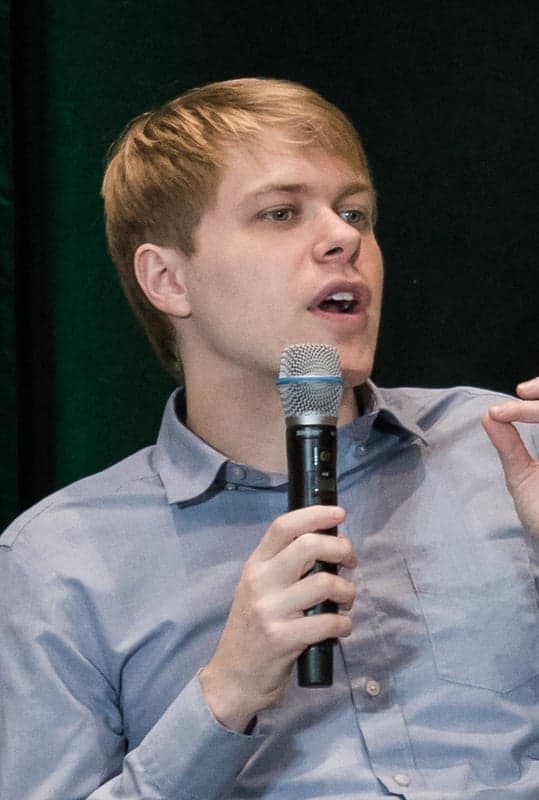
Dan Hendrycks
Director of the Center for AI Safety
The director of the Center for AI Safety, who created the GELU activation function and the MMLU and Humanity's Last Exam benchmarks.
Biography
Dan Hendrycks is an American machine learning researcher and director of the Center for AI Safety, a nonprofit in San Francisco. Raised in Marshfield, Missouri, he earned a BS from the University of Chicago in 2018 and a PhD in computer science from UC Berkeley in 2022.
His research covers machine learning safety, machine ethics and robustness. He is the main author of the 2016 paper that introduced the GELU activation function and the 2020 paper that introduced the MMLU language model benchmark. He created Humanity's Last Exam, a benchmark for evaluating large language models, with Scale AI. He is the safety adviser of xAI and an adviser to Scale AI, in both cases on a one-dollar salary, and he wrote the textbook Introduction to AI Safety, Ethics, and Society in 2024.
Notable contributions
Introduced the GELU activation function
Was the main author of the 2016 paper that introduced the Gaussian error linear unit, widely used in neural networks.
Introduced the MMLU benchmark
Was the main author of the 2020 paper that introduced Massive Multitask Language Understanding, a standard language model benchmark.
Created Humanity's Last Exam
Developed with Scale AI Humanity's Last Exam, a benchmark for evaluating the capabilities of large language models.
Directs the Center for AI Safety
Serves as director of the Center for AI Safety, a San Francisco nonprofit research organization.